
unslothはXPUに対応しているか?
unslothはXPUに対応している。それ用のインストール手順もありがたいことにUnslothが提供してくれている。

pytorchとtritonの組み合わせに注意した方がよさそう
今ちょうど2.9.0+XPUのtorchをインストールしているのだけど、こういうバージョン間の整合性は気を付けた方が良いらしい。
| torch (+xpu) | Intel extra | 入れるべき XPU Triton |
|---|---|---|
| 2.6.0 | intel-gpu-torch260 | pytorch_triton_xpu 3.2.0(Linux のみ) |
| 2.7.0 | intel-gpu-torch270 | pytorch_triton_xpu 3.3.0 |
| 2.7.1 | intel-gpu-torch271 | pytorch_triton_xpu 3.3.1 |
| 2.8.0 | intel-gpu-torch280 / intel | pytorch_triton_xpu 3.4.0 |
| 2.9.0 / 2.9.1 | intel-gpu-torch290 / 291 | pytorch_triton_xpu 3.5.0 |
| 2.10.0 | intel-gpu-torch210 | triton_xpu 3.6.0 |
| 2.11.0 | intel-gpu-torch2110 | triton_xpu 3.7.0 |
| 2.12.0 | intel-gpu-torch2120 | triton_xpu 3.7.1 |
Qwenをファインチューニングするには
Gated DeltaNetをチューニングする際、その効率を高めるには以下2つのコンポーネントが必要になる。
- causal_conv1d
- flash-linear-attention
これらをチューニングするために必要となるバージョンなのだけど、実は causal_conv1d に関してはCUDA専用でありXPU環境では使用できない。flash-linear-attention に関しては0.5.1にしておかないとTriton 3.5が対応してないため、注意が必要(執筆段階で 0.6.0 が最新)です。
なお、torch のバージョンを 2.9.0 にしてるのは、単純に Unsloth のXPU向けインストール手順で torch 2.9.0 の前提があったからであり、今後バージョンが上がっていけば普通にこれらのバージョンも上げることが可能だとは思われるんですが・・とりあえずは torch=2.9.0+xpu ならば上記の対応が無難なんだろうなと思います。
ちなみに、flash-linear-attention は絶対入れておいた方が良いです。torch直接の計算処理では 40s-50s かかってた処理が、最速で 10s 以下になります。当然ファンの音はうるさくなるわけですが(;´Д`)
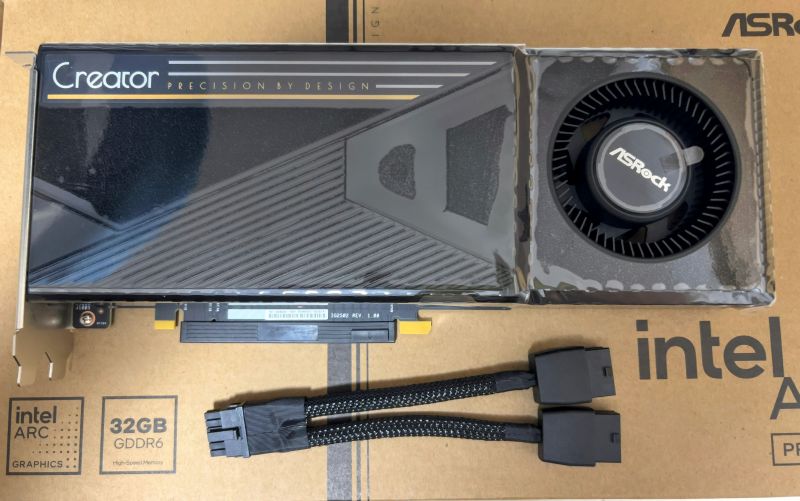
我が家のB70も本来Pro向け・Enterprise向けのGPUです。やっぱしそれなりの能力を発揮してもらわねば困るのは確かですね。今のところ Qwen3.5-4B は bf16 はカード一枚でちゃんと FineTuning できそうです。
コメント